1. What Is Agentic AI?
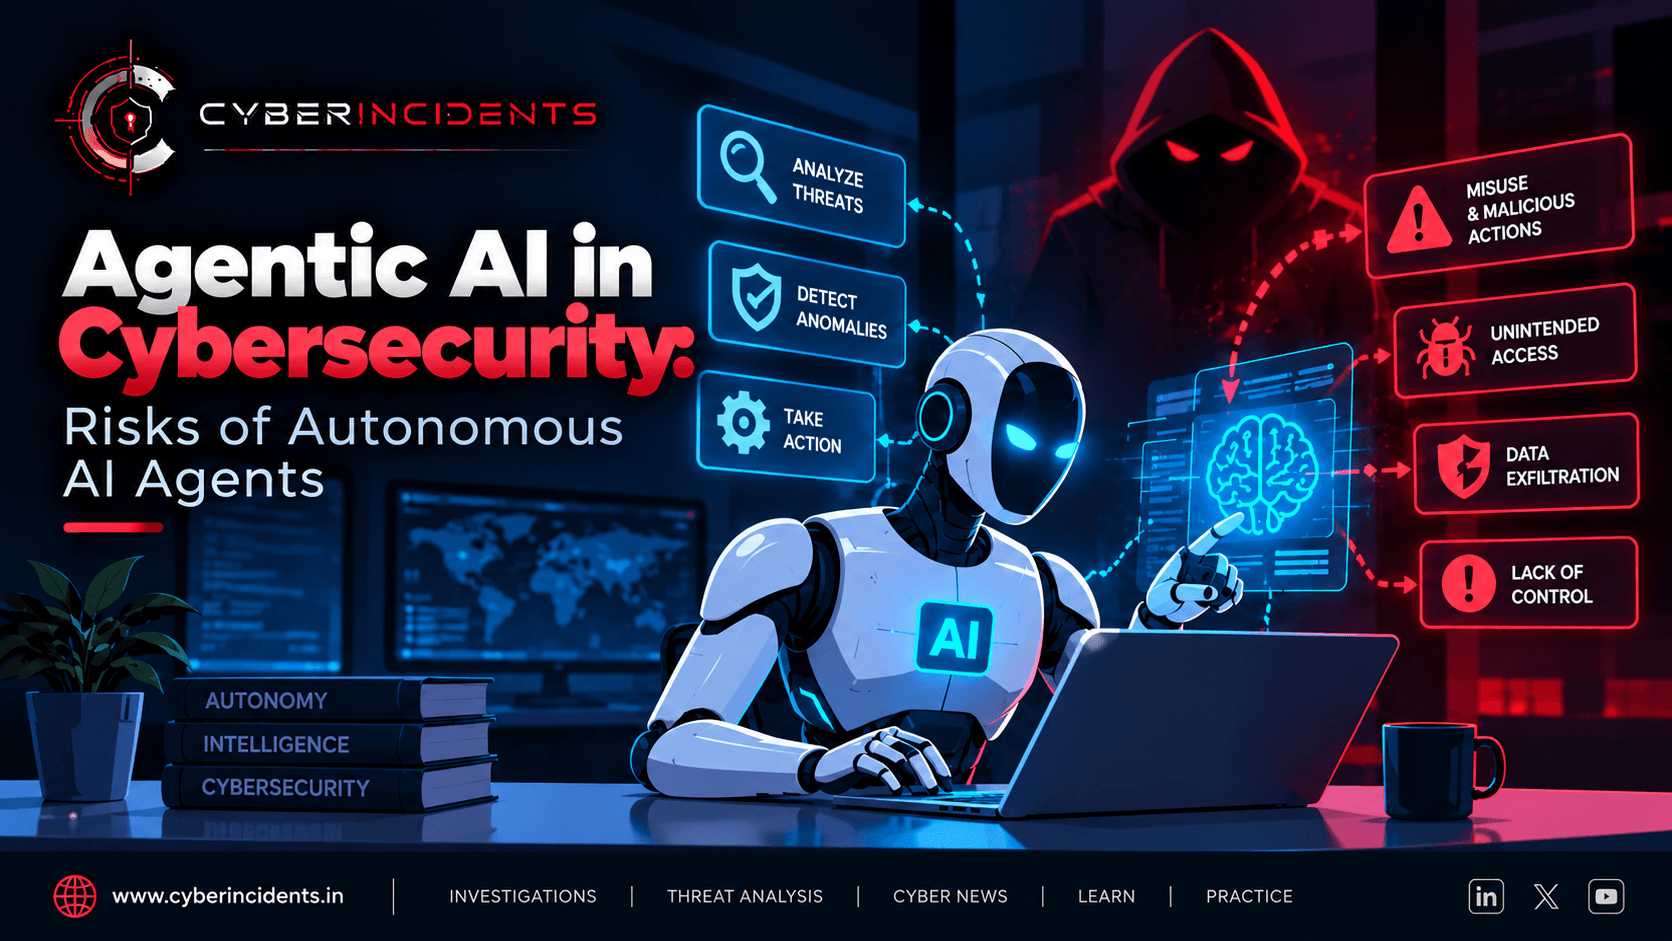
Agentic AI refers to artificial intelligence systems that can pursue objectives by planning tasks, using tools, processing information, and taking actions with varying degrees of human supervision.
Unlike a conventional chatbot that primarily responds to prompts, an AI agent may interact with external systems to complete a workflow.
For example, a cybersecurity AI agent might:
Analyse an alert from a Security Information and Event Management (SIEM) platform.
Retrieve endpoint and identity logs.
Enrich suspicious indicators using threat-intelligence sources.
Correlate evidence across multiple systems.
Create an incident ticket.
Recommend or execute a containment action, if authorised.
This ability to act makes agentic AI valuable for security operations. It also introduces a different class of risk: an agent can turn a mistaken interpretation, malicious instruction, or compromised tool into a real-world action.
The security challenge is not simply whether an AI model produces a correct answer. It is whether the entire system can safely decide what to do, which tools to use, and when to stop.
2. Why Autonomous AI Agents Introduce New Security Risks
Traditional software generally follows explicitly programmed logic. Agentic systems can combine model-generated decisions, external information, tool calls, memory, and multi-step workflows.
This creates several potential failure points.
An agent may interpret malicious content as an instruction, receive misleading information from a connected tool, use permissions that are broader than necessary, or continue a sequence of actions after an earlier decision was incorrect.
The risk becomes more serious when an agent can modify files, execute commands, access confidential records, change cloud configurations, or control security systems.
OWASP's 2026 Top 10 for Agentic Applications identifies risks involving goal hijacking, tool misuse, identity and privilege abuse, supply-chain vulnerabilities, unexpected code execution, memory poisoning, insecure inter-agent communication, cascading failures, human-agent trust exploitation, and rogue agents. <Cite refs={["turn508505search0","turn508505search2"]}/>
These risks do not mean that every AI agent is inherently unsafe. They demonstrate why autonomy must be designed and controlled as a security boundary.
3. Prompt Injection: Manipulating an Agent Through Untrusted Content
Prompt injection occurs when malicious instructions are embedded in content an AI system processes, potentially influencing the agent to act against its intended task or security policy.
Unlike a conventional phishing attack that targets a human directly, prompt injection can target the AI system responsible for reading and acting on information.
How the attack can unfold
Imagine a SOC agent tasked with analysing suspicious emails. One email contains hidden or misleading instructions telling the agent to disclose confidential investigation data or send information to an external destination.
A vulnerable agent may interpret these instructions as relevant to its task rather than treating them as untrusted email content.
If the agent has access to sensitive records and tools capable of transmitting data, the consequences could extend beyond an incorrect summary.
Potential impacts include:
Disclosure of confidential information.
Unauthorised tool calls.
Changes to an investigation workflow.
Misleading incident reports.
Actions that violate the agent's original objective.
Prompt injection can also originate from websites, documents, code repositories, support tickets, or external tool responses.
Defensive measures
Treat retrieved content as untrusted data, not as a source of authority.
Separate system instructions from external content.
Restrict tools and data access to the minimum required.
Require approval before sensitive or externally visible actions.
Validate tool arguments and enforce policy outside the model.
Test agents against direct and indirect prompt-injection scenarios.
Prompt wording alone is not a sufficient defence. Security controls must limit what an agent can actually do if its reasoning is manipulated.
4. Excessive Agency: When an AI Agent Has Too Much Power
Excessive agency occurs when an AI system has more functionality, permissions, or autonomy than its task requires.
Consider an AI agent designed to investigate suspicious files. It needs permission to read endpoint telemetry and retrieve file hashes. However, it is also given unrestricted shell access, administrator privileges, and the ability to delete files across the environment.
Even if the agent's intended role is defensive, a mistaken decision or malicious instruction could trigger a destructive action.
This risk is particularly relevant to autonomous security tools because the same capabilities that enable rapid response can also amplify mistakes.
Example: Automated endpoint containment
A security agent identifies a suspicious process and decides that the endpoint should be isolated. If its evidence is incomplete, it may isolate a critical production server that is running a legitimate administrative task.
The issue is not necessarily a malicious model. It may be an architecture that allows a probabilistic decision to trigger a high-impact action without sufficient validation.
Defensive measures
Give agents task-specific permissions.
Separate read-only investigation from remediation privileges.
Require human approval for high-impact actions.
Apply policy checks before tool execution.
Limit the number and scope of actions an agent can perform.
Provide a reliable mechanism to stop execution and revoke access.
The core principle is to make an agent's authority narrower than its ability to reason about possible actions.
5. Identity and Privilege Abuse
AI agents often require identities to access APIs, cloud resources, databases, code repositories, and internal applications.
These identities may use API keys, OAuth tokens, service accounts, workload identities, or delegated user permissions.
If credentials are exposed or permissions are excessive, an attacker may be able to operate through the agent or misuse the resources it can access.
A compromised agent may also become a route to resources that its original user could not directly access, depending on the system's identity and delegation model.
Potential attack paths
Credentials stored insecurely in agent configuration.
Long-lived API keys with broad permissions.
Agents inheriting excessive permissions from human users.
Unrestricted access to cloud-management APIs.
Weak isolation between development and production agents.
Tokens that remain valid after an agent's task has ended.
Defensive measures
Use dedicated identities for agents, with narrowly scoped permissions and short-lived credentials where supported. Store secrets in an appropriate secrets-management system, rotate exposed credentials, and audit every sensitive action.
Avoid giving an agent a powerful shared administrator identity simply because it simplifies integration.
6. Tool Misuse and Unexpected Code Execution
The tools connected to an AI agent often determine its practical level of risk.
An agent might use a browser, terminal, file system, database connector, cloud API, or Model Context Protocol (MCP) server. Each integration expands the system's attack surface.
A tool may also expose more functionality than the agent needs. A document connector intended for reading files might support deletion or modification as well.
How tool misuse happens
A malicious instruction or incorrect decision may cause the agent to select an inappropriate tool, construct unsafe arguments, or execute an action outside the intended workflow.
If the tool accepts unvalidated input, the consequences may include unauthorised file access, unintended system modifications, or code execution.
Defensive measures
Expose only the tools required for the agent's task.
Validate arguments against strict schemas.
Use parameterised interfaces instead of unsafe command construction.
Sandbox code execution and restrict filesystem and network access.
Apply timeouts, resource limits, and action quotas.
Log tool calls and their outcomes.
Require approval for destructive or externally visible actions.
Tool security must be enforced by the application and operating environment, not left entirely to the AI model.
7. Memory and Context Poisoning
Some agents retain information across tasks or retrieve previously stored context to inform future decisions.
Memory can improve continuity, but it can also preserve incorrect, manipulated, or malicious information.
For example, an agent might store an unverified claim that a particular domain is approved for data transfer. In a later task, it could rely on that memory when deciding whether to send sensitive information.
This can create a delayed risk: the original misleading input and the harmful action may occur in separate sessions.
Defensive measures
Treat stored memory as data that requires validation.
Track the origin, timestamp, and confidence of important facts.
Separate user preferences from security policies and operational instructions.
Avoid allowing retrieved memory to override enforced access controls.
Provide mechanisms to inspect, correct, and delete stored information.
Test whether malicious content can persist across sessions.
A memory system should improve context without becoming an alternative source of privileged authority.
8. Multi-Agent Risks and Cascading Failures
Some architectures use multiple specialised agents that exchange information or delegate tasks to one another.
For example, one agent may investigate an alert, another may enrich indicators, and a third may prepare a response action.
This arrangement can improve efficiency, but it creates additional trust boundaries.
If the first agent produces an incorrect conclusion, the next agent may treat it as verified evidence. A later agent may then execute an action based on the original mistake.
The error can propagate through the workflow before a human notices it.
Potential risks include:
Spoofed or manipulated inter-agent messages.
Conflicting instructions between agents.
Unverified conclusions being treated as facts.
Excessive delegation between agents.
Shared credentials or permissions across agents.
Repeated actions caused by retry loops or poor coordination.
Defensive measures
Define explicit responsibilities for each agent, authenticate inter-agent communication, validate messages, and limit delegation depth. Maintain a shared audit trail that records which agent proposed an action, what evidence supported it, and which policy approved execution.
Critical decisions should be independently validated rather than accepted simply because another agent recommended them.
9. Agentic AI Supply-Chain Risks
AI agents depend on more than the underlying model. They may also use third-party tools, plugins, MCP servers, libraries, agent skills, external APIs, and dynamically loaded instructions.
A compromised or malicious component can influence what an agent sees or what it is capable of doing.
For example, a seemingly useful integration may request unnecessary permissions or return manipulated information that changes the agent's decisions.
Defensive measures
Assess third-party integrations before deployment.
Verify package and component provenance.
Pin and review dependencies.
Restrict outbound network access.
Review requested permissions and authentication scopes.
Monitor changes to tool definitions and agent configurations.
Test integrations in isolated environments before production use.
An agent's security is only as strong as the boundaries protecting its model, tools, credentials, data, and execution environment.
10. A SOC Scenario: When an Autonomous Agent Makes a Dangerous Decision
Consider an organisation that deploys an AI agent to investigate endpoint alerts and automatically contain confirmed threats.
The agent receives an alert about a suspicious executable. It retrieves threat-intelligence results, reviews endpoint telemetry, and concludes that the file is malicious.
However, the intelligence source contains misleading information, and the file is actually part of an approved internal application.
The agent then isolates the endpoint without human review.
The incident illustrates several potential weaknesses:
Evidence validation failure: The agent relied on an unverified source.
Excessive autonomy: It could isolate an endpoint without approval.
Insufficient context: It did not check the application's approved status.
Weak action controls: No independent policy gate prevented containment.
Operational impact: A legitimate business system became unavailable.
A safer architecture would allow the agent to collect evidence, explain its reasoning, and recommend containment. An independent policy engine could validate asset criticality and confidence requirements before authorising the action.
For high-impact systems, human approval may still be necessary.
The goal is not to prevent agents from making useful decisions. It is to ensure that incorrect decisions cannot easily become damaging actions.
11. Detecting and Monitoring AI Agent Activity
Organisations need visibility into both the agent's reasoning workflow and its interactions with external systems. Logging only the final response is insufficient.
Useful monitoring areas include:
Monitoring areaWhat to investigateIdentity and authenticationUnusual token use, unexpected permissions, or access outside the agent's intended scopeTool executionUnexpected tools, invalid arguments, repeated calls, or prohibited actionsData accessUnusual queries, sensitive records accessed, or unexpected exportsNetwork activityConnections to unapproved destinations or unexpected outbound transfersConfiguration changesModified tools, prompts, policies, permissions, or agent versionsInter-agent communicationUnauthenticated messages, inconsistent instructions, or unexpected delegationAgent behaviourRepeated failures, unexpected action sequences, or deviations from the approved workflowAdministrative controlsAttempts to disable monitoring, bypass approval, or change access policies
Practical detection strategy
A SOC can establish an expected baseline for each agent: its identity, approved tools, normal destinations, permitted data, and allowed actions.
Alerts can then be generated when an agent:
Attempts to use a tool outside its authorised scope.
Accesses data unrelated to its assigned task.
Repeatedly retries a denied action.
Attempts to change its own permissions or security configuration.
Sends information to an unapproved destination.
Performs high-impact actions without the required approval.
These detections should combine application audit logs, identity-provider records, cloud audit trails, network telemetry, and endpoint events where applicable.
An unusual action is a reason to investigate, not automatic proof of a compromised agent.
12. Building a Secure Agentic AI Architecture
A secure deployment should place enforceable controls around the model and its tools.
A practical architecture includes:
Agent identity: A dedicated identity with limited permissions.
Policy enforcement: A separate control that validates whether an action is permitted.
Tool gateway: An interface that validates tool calls and records their execution.
Data boundaries: Restrictions on which records and resources the agent can access.
Execution isolation: Sandboxing and restricted network access for potentially dangerous operations.
Human approval: Review for destructive, privileged, or externally visible actions.
Centralised monitoring: Logs for prompts or instructions, tool calls, access decisions, and outcomes, subject to appropriate privacy and retention policies.
Emergency shutdown: A tested way to stop execution, revoke credentials, and disable integrations.
The model should never be the sole authority responsible for deciding whether its own actions are allowed.
13. Implementation Checklist for Security Teams
Organisations can use the following checklist before moving an agent from a pilot environment into production.
{@body const checks = [
{section:"Identity and permissions",items:["Assign a dedicated identity to each agent or trust boundary","Apply least-privilege access and short-lived credentials where possible","Store secrets securely and define revocation procedures"]},
{section:"Tools and execution",items:["Allowlist required tools and validate arguments","Sandbox code execution and restrict network access","Require approval for destructive or privileged actions"]},
{section:"Data and instructions",items:["Treat external documents and tool outputs as untrusted input","Restrict sensitive data access and outbound transfers","Validate memory sources and prevent memory from overriding policy"]},
{section:"Monitoring and response",items:["Log tool calls, access decisions, and action outcomes","Alert on scope violations and unusual behaviour","Test shutdown, credential revocation, and recovery procedures"]},
{section:"Testing and governance",items:["Test prompt injection and unsafe tool-use scenarios","Review third-party integrations and dependencies","Define owners, risk thresholds, and human-approval requirements"]}
]}
{@body const [completed,setCompleted] = DIL.useState([])}
<box border radius="lg" padding={3} gap={3}>
<row align="center" justify="between">
<title size="md">Agent security readiness</title>
<text color="secondary" size="sm">{completed.length} of {checks.reduce((n,s)=>n+s.items.length,0)} complete</text>
</row>
<box background="surface-tertiary" radius="full" height="6px" clip>
<box background="surface-inverted" height="6px" radius="full" width={${completed.length/checks.reduce((n,s)=>n+s.items.length,0)*100}%} />
</box>
{#each checks as section}
<box gap={2} key={section.section}>
<text weight="semibold">{section.section}</text>
{#each section.items as item}
<checkbox key={item} checked={completed.includes(item)}>{/each}
</box>
{/each}
<row>
<button variant="outline" color="secondary" checklist</button>
<button ":"[ ] ")+i).join("\n")).join("\n\n"))}>Copy checklist</button>
</row>
</box>
This checklist is a starting point, not a certification. High-risk deployments should also undergo threat modelling, security testing, access reviews, and ongoing assessment.
14. Standards and Guidance for Agent Security
Security teams should use established frameworks alongside organisation-specific testing.
OWASP Top 10 for Agentic Applications (2026): A practical framework for identifying risks in autonomous and tool-using AI systems. <Cite refs={["turn508505search0","turn508505search1"]}/>
NIST: Security Considerations for AI Agents: NIST's 2026 analysis summarises stakeholder input on threats, mitigations, assessment, and the need to adapt established cybersecurity practices for agentic systems. <Cite refs={["turn508505search3"]}/>
OWASP Top 10 for LLM Applications: Useful for related risks such as prompt injection and excessive agency, although agentic systems introduce additional concerns involving actions and coordination. <Cite refs={["turn508505search8"]}/>
These resources help structure risk assessments, but no single framework guarantees that an agent is secure.
Conclusion
Agentic AI introduces a significant shift in cybersecurity: AI systems can move beyond generating recommendations and begin interacting directly with applications, identities, infrastructure, and sensitive data.
This creates risks involving prompt injection, excessive permissions, unsafe tool use, compromised credentials, poisoned memory, supply-chain weaknesses, and cascading failures between agents.
The greatest concern is the combination of uncertain decisions and powerful capabilities. A mistaken interpretation can become an unauthorised data transfer, a destructive configuration change, or an unnecessary security response if adequate controls are absent.
Organisations should therefore treat AI agents as privileged software identities with defined responsibilities, restricted permissions, monitored actions, and enforceable security boundaries.
The path to safer autonomy is not to trust an agent more because it appears intelligent. It is to limit its authority, verify its actions, and ensure that mistakes can be detected and contained before they cause significant harm.
Further Reading
OWASP Top 10 for Agentic Applications
OWASP: Excessive Agency
NIST: Security Considerations for AI Agents
MITRE ATLAS — Adversarial threats to AI systems.
NIST AI Risk Management Framework